Neither half was a site
pantspantspants.biz went dark in 2009. Seventeen years later its owner had two things left: the domain name, and a folder of server leftovers salvaged in 2013. The folder held the blog's early photo library and a single ringtone; the rest was hosting scaffolding. No pages and no posts. This page is the record of a reconstruction built from that starting point. It pairs with our study of what a library's snapshot cannot promise: that page counts the gaps; this one shows what we did about them for a real site.
The survey came before any promise
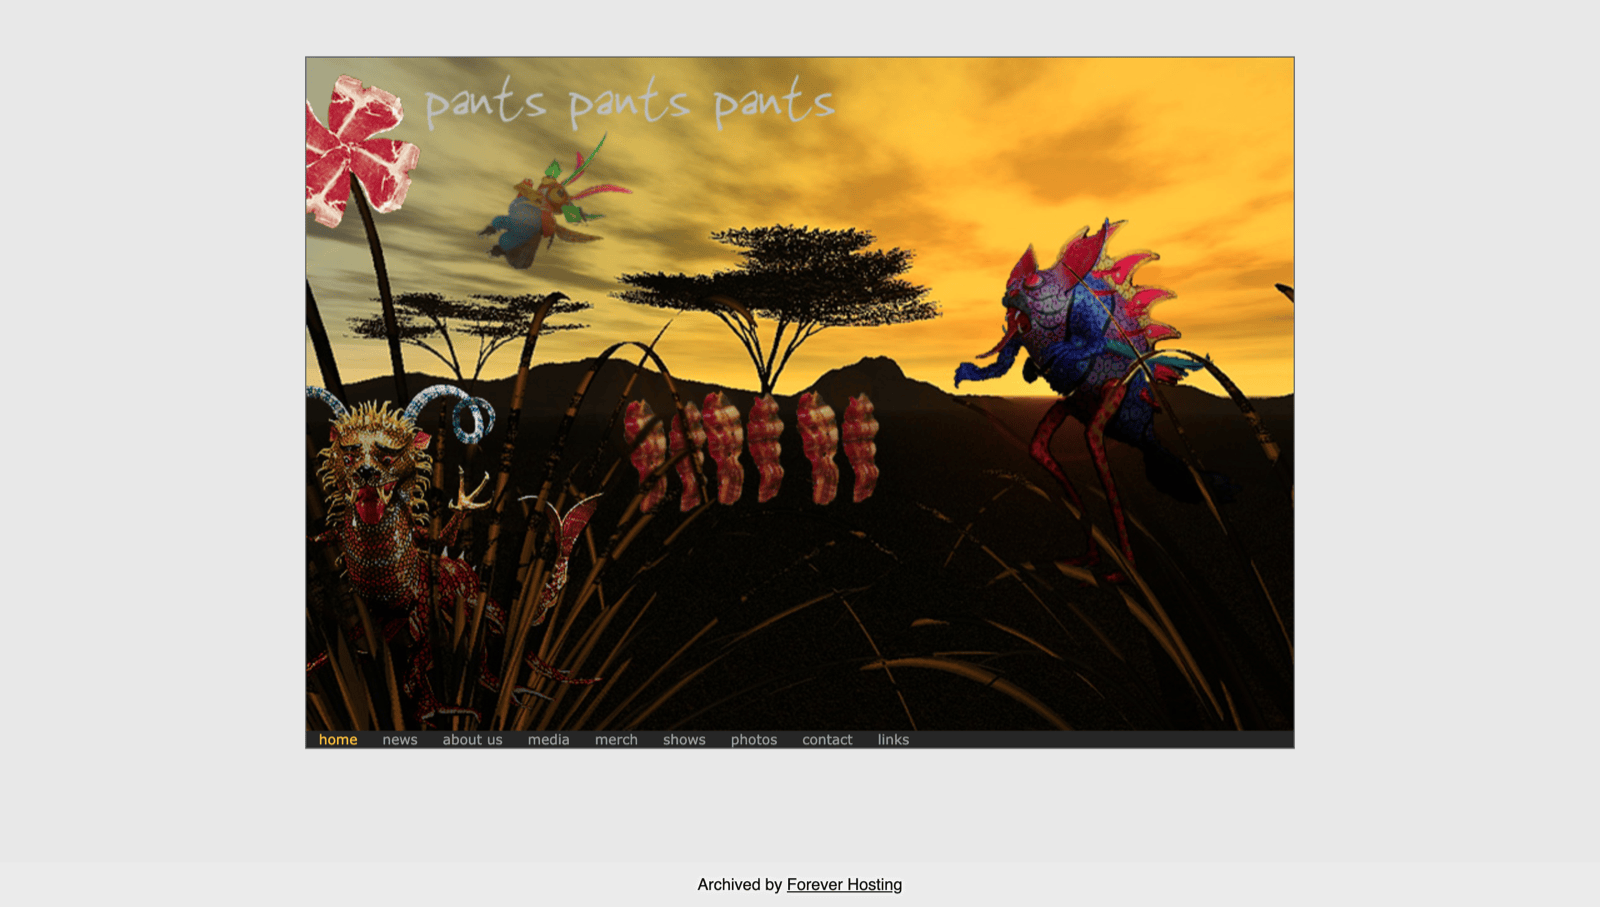
Before any work was agreed, we surveyed the public record. The Wayback Machine's index for the domain holds 1,183 captures of 593 distinct URLs, taken between May 2005 and October 2016. Read closely, the captures describe two different websites sharing one name. From 2005 to 2007 the domain was a hand-built site of 33 pages whose sections were Flash movies. From 2008 to 2009 it was a blog, 427 of its pages captured.
The verdict differed by era. The 2007 site could come back nearly whole; almost everything it needed was in the library, down to the videos and the music. The blog could not. The largest crawl took 205 blog pages on a single day in December 2008 and no supporting files at all. Of the roughly 310 photographs those pages reference, the library captured none, and it held none of the weekly ringtones either. Even the stylesheet was missing.
The merge
Then the folder. Its one tar file, dated February 2013, holds 643 entries: the blog's photo library through id 98, complete in that range, every photograph in all three sizes under its exact filename. It holds one ringtone. One Flash movie appears in both the folder and the library, byte for byte identical, each source vouching for the other. The library held the blog's words and none of its pictures. The folder held the pictures and none of the words. Neither half alone was a site.
What came back
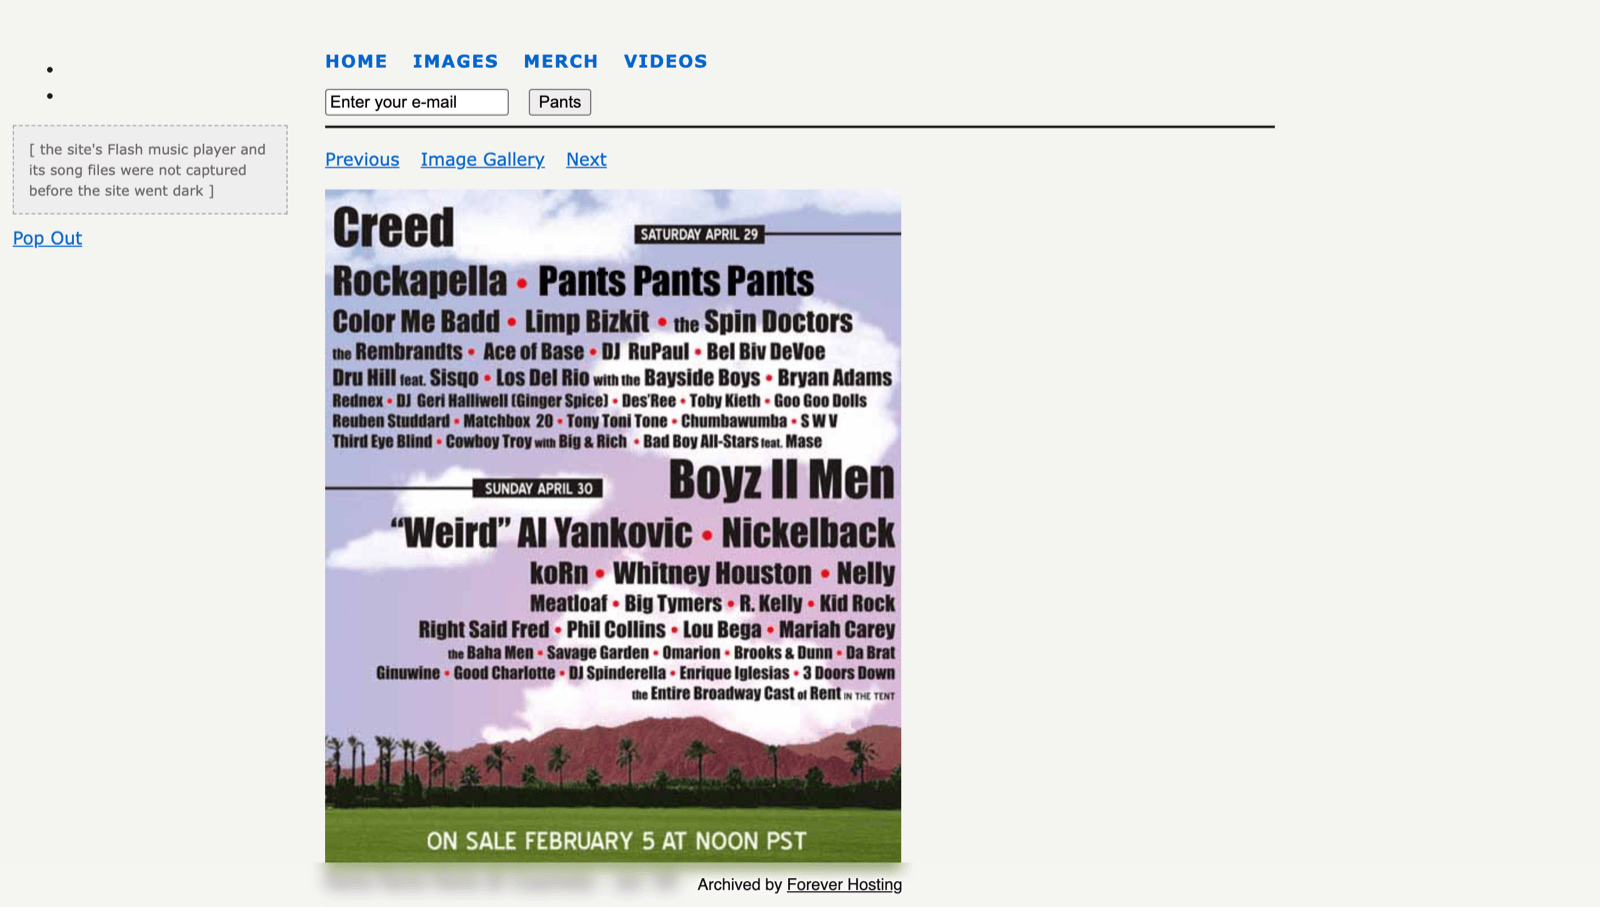
The archive is live at foreverhost.ing/pantspantspants.biz. The 2007 site plays its Flash through the Ruffle emulator, injected on the fourteen pages whose movies survive. The blog reads again: 153 of its roughly 186 posts carry their text, 119 from captured pages and 34 recovered from archived RSS feeds and tag pages that preserved words the page crawl never took. The early photo archive displays pixel-perfect from the backup, and 91 of the 259 captured photo pages have their photograph back. The surviving ringtone is served at its original path.
What stayed lost is said in place
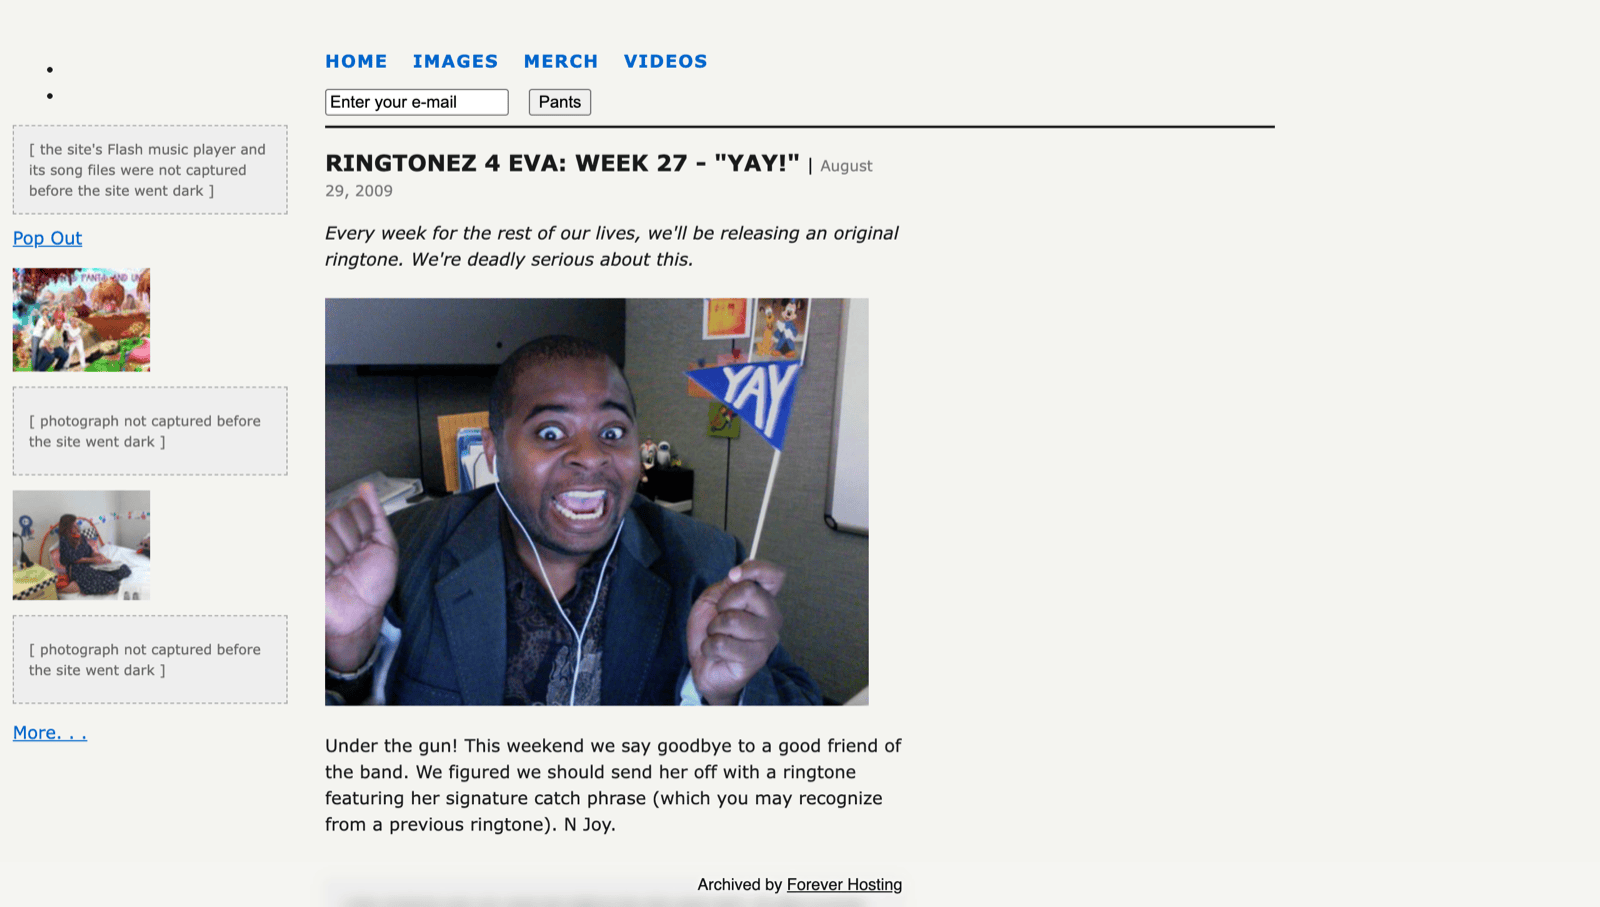
About 220 later photographs, ids 99 and up, exist in no source we could find; each shows a labeled note reading "photograph not captured before the site went dark." Twenty-eight of the weekly ringtones are lost, and the posts that announced them say so. Roughly 33 posts have no text in any source. 348 internal links point at pages that were never captured and resolve to an archival notice. The blog's stylesheet had to be written fresh from the markup, and the file says so in a header comment. Loss is part of this record, and the record states it where it happened.
The discipline underneath
The build's manifest records where every one of its 891 files came from: 559 from the Wayback Machine, each with its capture timestamp and checksum; 284 from the owner's backup; 40 marked reconstructions; 8 from our own pipeline. Before going live, the build faced an independent adversarial check and failed it twice. One failure was a page that received the Flash emulator although its movie never survived, a crash panel where a graceful fallback belonged. Another was a placeholder that would have hidden photographs that actually survived. The check protects recovered content as much as it catches defects, and it passed the build only after both failures were fixed.
If your site is already gone
We never promise recovery. The offer is a survey, not a rescue: bring what you have, and we will set the public record beside your files and tell you what they can rebuild together, and what they cannot, before any money moves. Here, a domain name and one folder of leftovers were enough.
Every figure above traces to the job's survey and build manifest; a claim ledger with reproduction steps accompanies this page.
Send us a URL: inquiries@foreverhost.ing